TL;DR: Poor email deliverability on outbound is almost always an infrastructure problem: too few inboxes carrying too much volume, domains ramped faster than reputation can build, and tracking or heavy HTML left on by default. Rewriting subject lines does not change where mail lands. The fix is to add sending capacity, strip the defaults, and hold volume flat while sending reputation recovers.
Reply rates fall, so the team rewrites the email. A shorter pitch, a new subject line, a different opening sentence. Two weeks later placement has not moved, and the rewrite gets blamed on the audience instead of the setup.
This pattern is common because email deliverability feels like a writing problem. The symptom shows up in a writing metric (replies), and the person who owns replies usually owns the copy. But mailbox providers decide placement before anyone reads a word. They decide it from sender reputation, recipient behavior, and how much mail a given inbox sends.
This post is a diagnostic. It covers what the symptom looks like, why copy rewrites feel productive and are not, the three upstream failures behind most spam placement, a test that separates a copy problem from an infrastructure problem, and the fix in the order it has to happen. If you want the checklist for auditing a setup, that lives in our cold email deliverability audit. This post is the mental model that tells you which problem you have.
What Poor Email Deliverability Looks Like in Practice
The first sign of weak cold email deliverability is rarely a bounce. It is a quiet, broad decline. Reply rate drops across several sequences at the same time, including ones with different offers and different audiences. When unrelated campaigns fall together, the cause is shared, and the thing they share is the sending infrastructure.
Opens will not tell you much. Apple's Mail Privacy Protection inflates open data, and tracking pixels are themselves a deliverability risk, as covered below. Replies, seed-inbox placement tests, and provider dashboards are the useful signals.
Here is how the common symptoms map to causes.
| Symptom | What it points to | What it does not point to |
|---|---|---|
| Reply rate falls across every sequence at once | Shared infrastructure: inbox load, domain reputation | A single weak subject line |
| Decline began within weeks of a volume increase | Volume ramp faster than reputation | Audience fatigue |
| Fresh inboxes perform well for a few days, then decay | Per-inbox volume too high | Message quality |
| Mail reaches Promotions but not Primary | Content and tracking defaults | Targeting alone |
| Mail reaches spam for new and old contacts alike | Domain or inbox reputation damage | Bad list quality (usually) |
Caption: Symptoms that show up in several campaigns at once usually come from shared infrastructure.
Spam placement in B2B outbound is also not binary. Mail can land in Primary, Promotions, or spam, and the split shifts by recipient domain. A team can look healthy in one provider's inbox and invisible in another's.
Google publishes the thresholds that matter. Under its email sender guidelines, senders sending 5,000 or more messages a day to Gmail accounts are expected to keep their user-reported spam rate below 0.10% and never reach 0.30%. Cold outbound spread across a handful of overloaded inboxes can approach those numbers faster than most teams expect, because each recipient who hits "Report spam" counts against a small denominator of daily sends.
Key stat: Google's guidelines set a 0.10% spam rate target and a 0.30% ceiling for bulk senders. At 0.30%, three recipients out of a thousand are enough to cross the line.
The guidelines apply formally to bulk senders. In practice, the same recipient behavior, spam reports and ignored mail, shapes placement for smaller senders too, just with less transparency about the threshold.
Why Copy Rewrites Feel Productive and Are Not
A copy rewrite gives you something to ship. It has a before and an after, a document someone can review, and a feeling of control. Infrastructure changes feel slower and more abstract, so they lose the internal prioritization contest even when they are the correct move.
There is also a measurement problem. Sending reputation lags. A change today shows up in placement over days or weeks, which means you cannot validate a copy change quickly. If you rewrite on Monday and replies are flat by Friday, you conclude the new copy also failed and rewrite again. After three rounds, the team has spent a month changing words while the actual cause, the sending pattern, has not changed at all.
Consider a hypothetical composite. A team sends the same volume from the same small set of inboxes every day. Replies slide over six weeks. The team tests four subject lines, two openers, and a shorter body. None of the variants wins, because all of them are being sent through the same overloaded inboxes with the same reputation. The test cannot find a winner because placement, not wording, is the variable that moved. This is an illustration, not a case study, and it is built to show the shape of the failure rather than any specific account.
The mental model that fixes this: inbox placement is decided mostly before the message is read, and it is decided by recipient behavior in aggregate. Providers watch whether recipients open, reply, delete unread, or report spam. They also watch authentication, sending volume patterns, and how consistent a sender is over time. Copy affects a small slice of that. Infrastructure affects most of it.
Reputation accumulates. Every send either adds to a track record of mail people want or to a record of mail they ignore or reject. That record attaches to the sending domain and, to varying degrees, the individual inbox. When it turns negative, better wording does not reverse it. Only a changed sending pattern does, and only after enough time for the new pattern to be observed.
Takeaway: Sending reputation is a lagging account of how recipients treated your past mail. You cannot edit your way out of it. You can only change what you send, from where, and how much, then wait.
The Three Upstream Failures Behind Spam Placement
Most cold-email placement problems trace to three causes. They are boring, which is why they get skipped.
Too Few Inboxes Carrying Too Much Volume
Outbound email infrastructure is a capacity system. Each inbox can send a limited number of cold messages per day before its behavior starts to look like a bulk sender to a provider. Our working ceiling is roughly 30 to 40 cold sends per inbox per day. That is a DemandLab operating rule, not a provider-published limit, and your own numbers should come from watching placement as you scale.
The arithmetic is where teams get caught. A volume target set by pipeline goals ("we need 800 contacts reached a day") gets pushed through whatever inboxes already exist. Nobody divides.
| Daily send target | Inboxes needed at ~35 sends/inbox/day | Typical shortcut that fails |
|---|---|---|
| 150 | 5 | 2 inboxes at 75 each |
| 350 | 10 | 4 inboxes at about 88 each |
| 700 | 20 | 6 inboxes at 115 each |
| 1,000 | 29 | 8 inboxes at 125 each |
Caption: Inbox count scales linearly with volume. The shortcut column is where reputation damage starts.
The fix for a volume problem is more inboxes spread across more domains, not squeezing more sends through each one. Adding capacity is cheap compared to the weeks lost recovering a burned domain.
Never send cold outbound from your primary company domain. Separate sending domains isolate the damage. If a secondary domain's reputation drops, the domain your customers and your sales team use for everything else is untouched.
Domains Ramped Faster Than Reputation Builds
A new domain and a new inbox have no history. Providers treat them cautiously, and the sending volume ramp is how you build the record that earns trust. A ramp is a schedule: low volume in week one, a measured step up each week, and a ceiling that you reach only when placement stays steady.
The common failure is treating the ramp as a switch. A domain is purchased, warmup runs for a few days, and the team loads a full campaign. The jump from near-zero to full volume looks to a provider like a freshly registered domain suddenly blasting, which is the pattern spammers also produce.
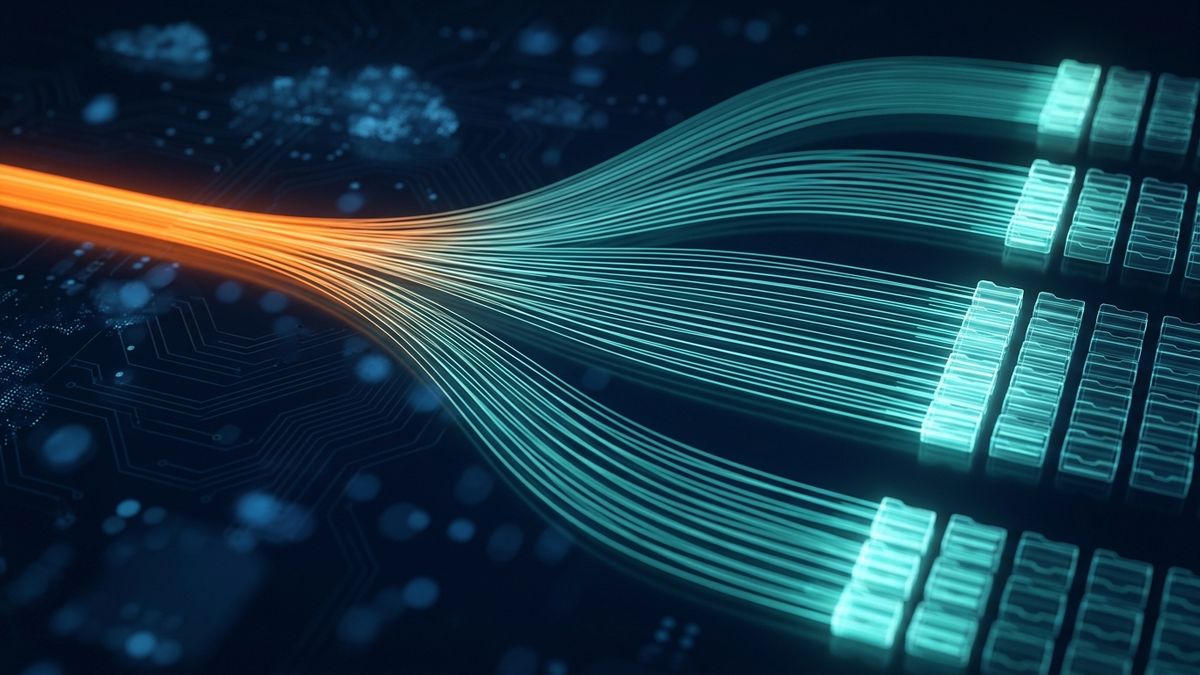
Caption: One concentrated spike of volume versus many steady, parallel streams. Spreading and steadying volume is what lets reputation build.
Email warmup tools help here, but only as support for a ramp. Warmup generates positive engagement signals while an inbox builds history. It does not offset an inbox that is carrying too much real volume, and it does not repair a domain that has already earned a poor record. Think of warmup as the floor under a ramp, not a replacement for the ramp.
Tracking and HTML Left On by Default
Sending platforms ship with defaults that are tuned for marketing email, not cold outreach. Open-tracking pixels, click-tracking link rewrites, and HTML templates are usually on until someone turns them off.
Each default adds a small signal. A tracking pixel loads an external image from a third-party domain. A rewritten link sends the recipient through a tracking domain that may itself carry a poor reputation, especially when it is shared across many senders. Heavy HTML, images, and logos make a one-to-one message look like a campaign. Individually these are minor. Stacked on top of high volume and a thin domain history, they tip placement from Primary into Promotions or spam.
Unsubscribe handling matters too. The RFC 8058 standard for one-click unsubscribe defines the header mechanism that mailbox providers look for, and Google's guidelines require it for bulk promotional senders. Even when you are not formally a bulk sender, a clear, working opt-out reduces spam reports, which are the most damaging signal you can generate.
Authentication belongs on this list as a baseline, not a diagnosis. SPF, DKIM, and DMARC need to be in place and aligned before anything else matters, and DMARC in particular is now an expectation from large providers. The audit post covers how to verify them. This post assumes they are correct and asks what is left when they are.
How to Tell an Infrastructure Problem From a Copy Problem
The practical question is how to know which problem you have before you spend a month on the wrong one. Run a short test with one variable changed at a time. The principle: split by inbox and domain, not by message.
| Test | Result | Conclusion |
|---|---|---|
| Send the same copy from a fresh inbox on a clean domain at low volume | Places well | Infrastructure or volume problem on the original inboxes |
| Send the same copy from a fresh inbox on a clean domain at low volume | Also lands in spam | Content, tracking, or list problem |
| Send new copy from the original inboxes | Placement unchanged | Not a copy problem |
| Send the same copy from the original inboxes at 30% of the prior volume for two weeks | Placement improves | Volume was the cause |
| Strip tracking and HTML, send plain text from the original inboxes | Placement improves | Defaults were the cause |
Caption: Change one variable at a time. Fresh-inbox tests isolate infrastructure from content.
Seed-inbox testing helps if you keep it consistent. Maintain a small set of test addresses across major providers, send from the same inboxes you use for real campaigns, and log placement over time. A trend line matters more than any single reading.
Watch domain reputation through the provider's own dashboards where available, such as Google's Postmaster Tools, and track spam-report rates against the thresholds above. If a domain's reputation is poor and the inbox count is low, the diagnosis is already clear without any copy test.
Channel coordination plays a role as well. When email and LinkedIn run as one system, as laid out in our multichannel outbound sequence build, you can lower email volume per inbox without lowering total outreach, because the other channel carries part of the load. That makes the volume reduction the fix requires much less painful.
The Email Deliverability Fix, in Sequence
The recovery order matters. Doing the right things in the wrong order wastes weeks.
- Stop adding volume. Freeze new campaigns and list loads on affected inboxes. Do not increase anything while diagnosing.
- Add capacity. Provision additional inboxes on separate sending domains until each inbox sits at or below your working ceiling. Capacity should exist before you need it.
- Strip the defaults. Turn off open tracking and click tracking, send plain text or minimal HTML, and remove images and logos from cold messages.
- Hold volume flat. Keep sending volume level for several weeks. Reputation recovers when providers see consistent, wanted mail at a steady rate, not when volume dips for a day and then returns.
- Release in small steps. Once placement is steady, increase per-inbox volume gradually and watch placement after each step. If it slips, step back.
Holding volume flat is the step teams resist most, because it feels like doing nothing. It is the opposite. Sending reputation is rebuilt through accumulated evidence, and evidence only accumulates if the pattern stays consistent long enough to be observed. Changing volume every few days resets the clock.
Pause or retire inboxes that have fallen into persistent spam placement rather than continuing to push mail through them. A damaged inbox that keeps sending adds negative history to the shared domain. Retiring it and replacing capacity elsewhere is cheaper than the slow decay.
A few things to leave alone during recovery: do not change authentication records without a reason, do not swap sending platforms mid-recovery, and do not rewrite copy at the same time as changing infrastructure. If two variables move together, you cannot tell which one worked.
Once placement is stable, then personalization work pays off. Our guide to cold email personalization at scale covers that layer. It belongs after the infrastructure is sound, because a well-personalized email that lands in spam is still invisible.
What to Monitor While You Hold Steady
Holding volume flat is not passive. Review a short set of signals every week and write the numbers down, because recovery is slow enough that memory will mislead you.
- Placement by recipient provider. Track Primary, Promotions, and spam separately for each major provider in your seed set. A gain at one provider and a loss at another is common during recovery.
- Reply rate by inbox, not by campaign. Campaign averages hide the single inbox that is still dragging the domain. Per-inbox numbers show which ones are healing and which ones to retire.
- Spam-report rate where the provider shows it. Compare it to the 0.10% target. A rising line is a reason to cut volume further, whatever the reply rate says.
- Bounce rate. Hard bounces tell you the list is stale, which is a separate problem from reputation but one that compounds it. Remove invalid addresses before they send another message.
Set a rule in advance for stepping volume up: for example, placement steady for two consecutive weeks before any increase. Deciding the rule before you are tempted keeps the schedule from bending to a quarter-end pipeline target.
When It Really Is the Copy
Copy is not irrelevant. A message that nobody wants produces spam reports and ignored mail, and those behaviors feed reputation. If the offer is mismatched to the recipient, targeting is poor, or the message is easy to mistake for a template blast, that does hurt placement over time.
The order of operations is the point. Fix capacity, ramp, and defaults first, because they set the ceiling on everything else. Then work on relevance and copy, because it determines what happens to mail that reaches the inbox. Teams that do it the other way around spend their effort on the part with the smallest effect on placement.
A useful test: if a fresh inbox on a clean domain, sending at low volume with tracking off, still lands in spam with your current copy, the content or the list is the problem. If the same copy places well from that inbox, the original setup is the problem. That one test settles most arguments.
Frequently Asked Questions
Why are my cold emails going to spam even though my copy is fine?
Spam placement is driven mostly by sender reputation, volume per inbox, and recipient behavior, not by wording. If several campaigns decline together, the shared sending infrastructure is the likely cause. Test the same copy from a fresh inbox on a clean domain at low volume to confirm.
How many cold emails can one inbox send per day?
Providers do not publish a per-inbox cold email limit. Our working ceiling is roughly 30 to 40 cold sends per inbox per day, and you should adjust it based on observed placement. Divide your total daily volume by that ceiling to find how many inboxes you need.
How long does it take to recover sending reputation?
Expect weeks, not days. Reputation rebuilds when providers observe steady volume and wanted mail over time, so the recovery clock restarts whenever volume swings. Add capacity first, then hold volume flat until placement stabilizes.
Does email warmup fix deliverability?
Warmup supports a volume ramp by generating positive engagement while an inbox builds history. It does not offset an inbox that carries too much real volume, and it does not repair a domain that already has a poor record. Treat it as one input to a ramp, not the fix.
Do spam trigger words still matter for inbox placement?
Rarely as the primary cause. Tracking pixels, link rewriting, heavy HTML, volume, and spam reports weigh more heavily than individual words. Fix those first, then look at wording.
What is the difference between domain reputation and inbox reputation?
Domain reputation aggregates the behavior of every inbox sending on that domain, while inbox reputation reflects a single address. One overloaded inbox can drag down the shared domain, which is why cold outbound should run on separate sending domains from your primary one.
Key Takeaways
- Poor email deliverability that hits several campaigns at once usually comes from shared infrastructure, not from any one message.
- Divide daily send volume by a per-inbox ceiling (our working number is 30 to 40) to find how many inboxes you actually need.
- Ramp new domains on a schedule. A warmup tool supports a ramp but does not replace one.
- Turn off open and click tracking and send plain text on cold outbound.
- Test with a fresh inbox on a clean domain to separate infrastructure from content.
- During recovery, add capacity, hold volume flat, and change one variable at a time.
Deliverability is the layer under every outbound system. If yours is leaking placement, the GTM Maturity Assessment shows where your outbound infrastructure stands in about five minutes, and if you want us to map the capacity and ramp for your setup, book a GTM analysis.
Sources
- Google, Email sender guidelines (2024): spam-rate thresholds and authentication requirements for bulk senders
- IETF, RFC 8058: Signaling One-Click Functionality for List Email Headers (2017): the one-click unsubscribe header standard
- Wikipedia, DMARC: background on DMARC authentication policy
- Google, Postmaster Tools: domain and IP reputation monitoring for Gmail recipients