Every company building content for AI search has the same question: is my brand actually showing up in AI-generated responses? The market has answered that question by producing a wave of paid dashboards. Before you buy one, consider this — the underlying data is not proprietary. AI search visibility tracking is a practice you can stand up yourself, in a week, using public APIs and a spreadsheet. This post shows you exactly how.
The principle is the same one that drives the grounding queries methodology: the AI retrieval layer is directly observable. AI-generated responses are not black boxes. They are text you can query, log, parse, and count. The citation-share metric that a paid dashboard shows you is calculated from that text. This guide shows you how to build your own measurement system, what the numbers actually look like, and where a paid tool earns its cost — so you can make a real decision instead of an anxious one.
Why Every Tool Listicle Is the Wrong Starting Point
Search for "ai search visibility tracking" and you will find listicles. Frase. Otterly. Stackmatix. Omnia. llmpulse. Every page-one result is either a vendor's own product page or a paid-tool ranking article. None of them explain how to measure AEO performance before you buy anything.
That framing is backwards.
AI-generated responses are increasingly part of how B2B buyers research categories and build shortlists. When a prospect asks ChatGPT or Gemini which signal-based outbound tools are worth evaluating, whether your brand appears in that response determines whether you exist in that moment of consideration. The need to track this is genuine.
But the tools are selling automation and a dashboard around data that lives behind a public API. The Gemini API and the OpenAI API return the full response text — the same text the paid tool's crawler is reading. If you are not yet tracking your citation rate at all, you do not need a dashboard first. You need to establish a baseline. A dashboard that tells you your citation rate dropped 8 points last month cannot tell you why, and it cannot tell you what to do about it. That requires reading the actual responses.
The right sequence: instrument yourself, establish your baseline, understand the pattern, then decide whether automation is worth the cost.
Key point: A paid tool shows you the number. Reading the responses shows you the reason.
What AI Search Visibility Tracking Actually Measures
Before building anything, it is worth being precise about the metric. AI search visibility tracking is not a single number — it is three distinct measurements, each telling you something different.
The Three Metrics That Matter
Citation rate is the headline number. Of a defined sample of queries relevant to your category, what percentage return a response that cites your brand? A brand cited in 14 of 100 sampled queries has a 14% citation rate. This is your AI citation tracking baseline.
Citation position tells you how authoritative your brand appears within cited responses. A citation in the first sentence of an AI response carries far more weight than a parenthetical mention after five competitors have already been named. Position matters for conversion, not just awareness.
Query coverage tells you whether your content strategy is aligned with what buyers are actually asking. If your content answers 60% of the queries in your target set, that is a content strategy problem. If your content answers 100% but your citation rate is 5%, that is a content quality or distribution problem. The distinction matters for knowing what to fix.
| Metric | What it measures | How to calculate | Why it matters |
|---|---|---|---|
| Citation rate | Brand presence in AI responses | (Cited responses / total sampled) × 100 | The top-line visibility number |
| Citation position | Relative authority within a response | Rank position of first brand mention | Conversion proxy — early citations drive more action |
| Query coverage | Content-to-query alignment | (Queries your content answers / total query set) × 100 | Identifies content strategy gaps before they become visibility gaps |
What AI Citation Tracking Is Not
It is not the same as organic search rank. You are not trying to get a blue link. You are tracking whether the AI selects your content as a trusted source when synthesizing its response.
It is not about brand name appearances alone. A mention without a citation is awareness. A citation means the AI is treating your content as an authoritative source for the query. Track citations specifically — not name drops.
For context on what makes content citable by AI systems, the Answer Engine Optimization guide covers the technical and structural requirements in depth.
How to Build Your Own AI Visibility Tracking System
This is not an engineering project. The full DIY build takes a few hours to set up and about 30 minutes per week to run. Here is the complete process.
Step 1: Define Your Query Set
Start with 20–50 queries. Use the exact language your buyers use, not your marketing language.
Organize your queries into three intent categories:
- Category-definition queries: "what is [your category]", "how does [your category] work", "what is the difference between [your category] and [adjacent category]"
- Comparison queries: "best [category] tools for [company size or role]", "[your brand] vs [competitor]", "[your category] alternatives"
- Use-case queries: "how do I [specific problem your product solves]", "can AI [task your product handles]"
Put these in a spreadsheet with columns: Query | Intent Category | Buying Stage | Priority (High / Medium / Low). Keep the set small enough that you can actually review responses each week, not just count them.
Step 2: Sample the Responses
Use the Gemini API or OpenAI API to run each query programmatically. This is a basic API call. No machine learning expertise required.
Here is a minimal Python example using the Gemini API:
import google.generativeai as genai

genai.configure(api_key="YOUR_GOOGLE_API_KEY")
model = genai.GenerativeModel("gemini-2.0-flash-001")

queries = [
    "what is the best clay alternative for b2b outbound",
    "how does signal-based lead scoring work",
    "hubspot vs salesforce for b2b saas",
]

results = []
for query in queries:
    response = model.generate_content(query)
    results.append({
        "query": query,
        "response": response.text,
    })
According to the google-generativeai Python SDK documentation, generate_content returns a GenerateContentResponse object — the .text attribute gives you the full plain-text response. Log the complete text, not just a summary. The full text is where you find citation context and competitor mentions.
The grounding query map schema provides a useful starting structure for organizing your query set by intent category — the same framework applies here.
Run your full query set weekly. AI model responses shift over time as models are updated. A single snapshot tells you your citation rate at one moment. A weekly run tells you whether your AEO work is moving the number in the right direction.
Step 3: Parse and Store
Use simple string matching to check each response for your brand:
# Continuing from the sampling loop above
brand_terms = ["DemandLab", "demandlabagency.com", "Chris Arden"]

for result in results:
    cited = any(term.lower() in result["response"].lower() for term in brand_terms)
    result["brand_cited"] = cited
Store each result in Airtable or Google Sheets with these columns:
| Column | What to log |
|---|---|
| Query | The exact query text |
| Date | Sampling date |
| Response Text | Full AI response |
| Brand Cited | Yes / No |
| Citation Position | Early / Mid / Late / None |
| Competitor Citations | Comma-separated list of competing brands mentioned |
| Notes | Anything notable about the response framing |
This structure supports trend analysis over time without requiring a database. The "Notes" column is where the real insight comes from — when you read the responses, you learn what the AI is saying about your category and your competitors, not just whether your name appears.
Step 4: Calculate Your Citation-Share Rate
Formula: (queries where brand was cited / total queries sampled) × 100
Run this for each weekly batch. Track the number over time. This is your citation-share metric: the AI-era equivalent of organic share of voice.
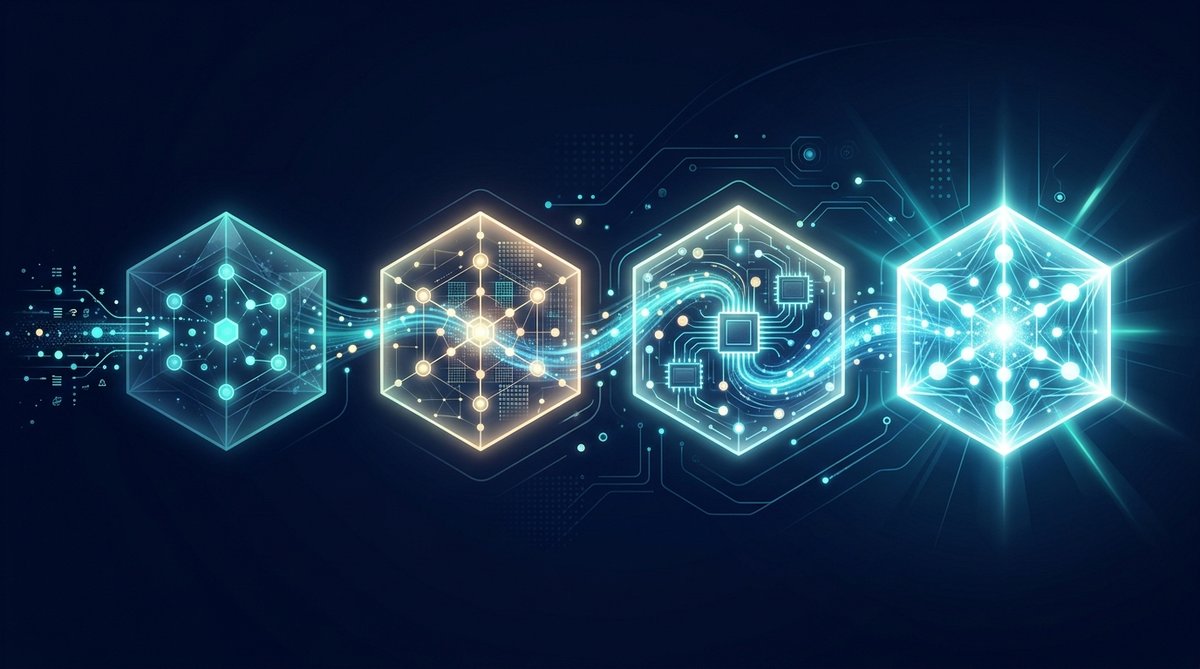 The four-step DIY visibility tracking build: query set definition flows into API sampling, into response logging, into citation-share calculation.
The Citation-Share Metric: What It Looks Like in Practice
A worked example makes this concrete.
Sample: 50 queries across category-definition, comparison, and use-case intent
Results: Brand cited in 8 of 50 responses
Citation-share rate: 16%
What does 16% mean? Your content answers roughly 1 in 6 of the questions buyers ask in your category. Whether that is good depends on how competitive your category is and how recently you started building content for AI search.
There are no published industry benchmarks for citation share as of September 2026 — the category is too new. In practice, with new AEO programs we have tracked, teams starting from scratch typically see 0–5% citation share in the first month and reach 15–25% within 90 days of consistent, structured publishing. Those numbers come from categories with moderate competition. In highly competitive categories, 10% is a meaningful position.
Reading Citation Position
The position within the response matters as much as whether you appear at all.
| Position | Signal strength | Typical context | Action |
|---|---|---|---|
| Early (first paragraph) | High | AI leads with your content as the primary source | Monitor and protect — this is authority |
| Mid-response | Medium | Your brand is part of the answer, alongside others | Strengthen the specific content being cited |
| Late-response | Low | Supporting reference, after competitors are framed | Re-examine content depth for those queries |
| Not cited | None | Content is not being used for these queries | Check coverage: does relevant content exist? |
What Moves the Number
Three inputs reliably shift citation rate upward:
- Publishing content that directly answers queries in your target set at a depth that exceeds what already ranks
- Earning inbound links from sources that AI systems already treat as high-authority
- Ensuring your content is technically accessible — proper crawlability, clean HTML, schema markup
For the technical and structural requirements, the Answer Engine Optimization guide covers the full framework. That pillar is worth reading alongside this one.
What Paid Dashboards Add That the DIY Build Does Not
There are four things a paid LLM visibility monitoring tool genuinely adds — and one thing it does not.
Automated sampling at scale. A DIY build running 50 queries weekly is feasible with a cron job and a Google Sheet. Running 5,000 queries across 10 product categories requires infrastructure that the average marketing team should not build themselves. Paid tools handle this.
Competitor citation tracking. The most valuable feature most tools offer: not just "was I cited?" but "who was cited instead of me, and in what context?" This is harder to build yourself because it requires identifying and systematically tracking your entire competitive landscape across a large query set. A paid tool with competitor monitoring is worth it specifically for this capability.
Multi-model coverage. Tools like Otterly and llmpulse (as of September 2026) sample across Gemini, ChatGPT, Claude, Perplexity, and others simultaneously. A DIY build typically covers one or two models. If your category conversation happens significantly across multiple platforms, multi-model coverage is a real advantage.
Alerting. Paid tools notify you when citation rate drops significantly. This is useful for catching the impact of a model update or a competitor's content surge in near real-time.
| Capability | DIY build | Paid tool | Verdict |
|---|---|---|---|
| Citation rate tracking | Yes, up to ~200 queries/week | Yes, at scale | DIY sufficient to start |
| Competitor tracking | Manual only | Automated | Tool advantage — real value |
| Multi-model sampling | 1–2 models | 5+ models | Tool advantage, if needed |
| Alerting | Manual check | Automated | Tool advantage for busy teams |
| Diagnosis (why did the number change?) | High — reading responses | Low — dashboard only | DIY always wins here |
| Cost | Near-zero (API costs) | $200–800/month | Tool only justified at scale |
What they do not add: explanation. A dashboard that shows your citation rate dropped 8 points last month cannot tell you why. Did a model update de-prioritize a type of content you rely on? Did a competitor publish something that displaced you? Diagnosis requires reading the actual responses — which is what the DIY build forces you to do.
The Build-vs-Buy Decision Framework
Here is the simple decision rule:
| Scenario | Recommendation | Why |
|---|---|---|
| You have never measured your citation rate | Build DIY first | Baseline before dashboard. You need to understand the data before you automate it. |
| Running fewer than 300 queries/week | Stay DIY | API costs are negligible; the reading discipline is an asset. |
| Need competitor tracking across 10+ brands | Consider a paid tool | This is genuinely hard to build yourself at scale. |
| Running 500+ queries/week across 5+ models | Move to paid | Infrastructure and aggregation justify the cost. |
| Your team will not read raw responses | Reconsider | A dashboard with an unread alert is useless. Fix the workflow first. |
For ChatGPT brand monitoring specifically, the OpenAI API (/v1/chat/completions) is accessible in the same way as the Gemini API — the Python example above maps directly with the openai client library. Multi-platform coverage is a matter of adding a loop across providers, not a fundamentally different approach.
Start with the DIY build. It costs almost nothing, forces you to understand what the AI is actually saying about your category, and gives you a real baseline number. When you outgrow it — when you have too many queries to run manually and you need competitor alerts that run without someone remembering to check — move to a tool. Buying a dashboard before you know your baseline number is paying for a scoreboard before you know what game you are playing.
If you want a diagnostic view of where your overall GTM system stands, including how AI search fits into your pipeline, the GTM Maturity Assessment maps this in about five minutes.
Frequently Asked Questions
What is AI search visibility tracking?
AI search visibility tracking is the practice of measuring how often and in which contexts your brand is cited in AI-generated search responses. It uses a defined set of queries, programmatic API sampling, and response parsing to calculate a citation-share metric across LLM-powered answer engines like Gemini and ChatGPT.
How do I track brand mentions in AI search without a paid tool?
Run a structured query set against the Gemini or OpenAI API using a simple Python script. Log the full response text for each query and use string matching to detect your brand name. Store results in a spreadsheet with columns for date, query, response, citation flag, and competitor mentions. Run weekly and calculate your citation-share rate from each batch.
What is AI citation tracking?
AI citation tracking is the process of determining whether AI systems are using your content as an authoritative source when generating responses. A citation means the AI references your content specifically, not just that your brand name appears somewhere in the response. Tracking citations separately from brand mentions tells you whether your content is earning authority, not just awareness.
How do I measure AEO performance?
Measure AEO performance using three metrics together: citation rate (what percentage of your target queries return a response citing your brand), citation position (how early in the response your brand appears), and query coverage (what percentage of your target query set your content actually answers). All three together give a complete picture; any one in isolation is misleading.
What is share of voice in AI search?
Share of voice in AI search is the percentage of relevant queries for which your brand receives a citation in the AI-generated response, relative to your total query sample. A brand cited in 16 of 100 sampled queries has a 16% citation share. It is the AI-era equivalent of organic share of voice, and it is calculated the same way: citations won divided by citations available.
Do I need an LLM visibility monitoring tool?
You do not need a paid LLM visibility monitoring tool to start. The core data — query responses from Gemini and ChatGPT — is accessible through their public APIs. Paid tools earn their cost when you need automated sampling at scale (500+ queries/week), multi-model coverage, or automated competitor tracking. If you are running fewer than 300 queries weekly, a DIY build is cheaper and more instructive.
Sources
- Google, google-generativeai Python SDK documentation — Reference for the
GenerativeModel.generate_contentmethod and response structure used in the DIY sampling example. - DemandLab, Grounding Queries: See the Searches AI Runs Before It Cites You (2026) — Establishes the observation-first framework this post builds on; demonstrates that the AI retrieval layer is directly observable through public API fields.
- DemandLab, Answer Engine Optimization: The 2026 Complete Guide (2026) — Full framework for structuring content to be citable by AI answer engines; the technical complement to the measurement approach here.
Take the GTM Maturity Assessment — a five-minute, role-specific diagnostic that shows where your AI search and pipeline systems stand today.